
Linjiang Chronicles.
A whole life, one paper screen.
A premium ancient-life simulation for iPhone — take the imperial exams, manage a granary through flood season, and live with the consequences of 711 decisions. Built in Godot by AI agent teams, with every branch machine-audited.
What is it? A reading-first life simulation set in a river county of ancient China. You steer one life across 8 chapters — scholarship, family, disaster relief, and twenty possible endings — through a paper-and-vermilion phone UI designed for one-handed play.
Godot 4.6 · iPhone portrait · premium (buy once) · no ads, no gacha, no live-service hooks.
The design idea: decisions you can read
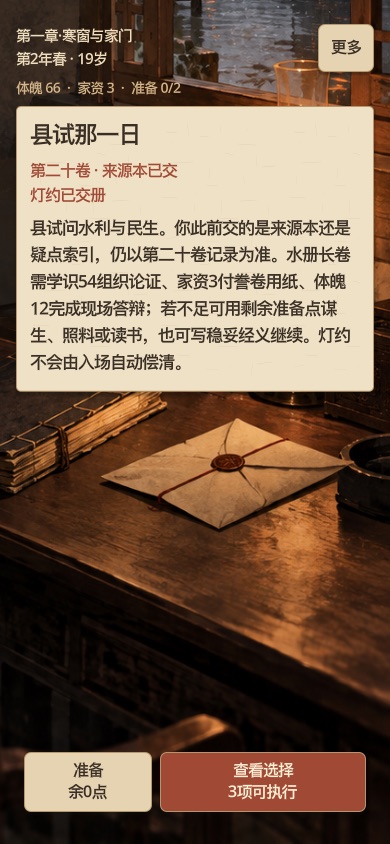
Most mobile "choices" games hide their systems behind timers. Linjiang goes the other way: every decision shows its cost before you commit. A choice page is a reading page — the plan, the receipts, and the consequences are all on the paper. The UI contract is explicit: selecting never executes; only the vermilion seal at the bottom commits. Two adjacent options always fit on screen as fixed-width cards, and every prep step is reachable in a tap — no hidden menus, no forced scroll-hunting on a 320-pixel-wide phone.
Systems worth knowing
Three life routes, one county
You pick a path through county life — scholarship first among them — and the game tracks material holdings, health, reputation, and the two long-arc relationships (a magistrate's aide and a merchant's daughter are the current pair). Routes cross: an exam decision can cost you the grain you needed for flood relief.
The granary problem (chapter six)
Chapter six turns disaster relief into a finite-inventory puzzle: five household funds buy twelve sacks of grain, once. First distribution splits into three outcomes; the second wave pressures you to save workers or sell stock. The autumn-flood relief requires that four sacks actually remain — the game audits your receipts, not your intentions. No amount of reputation or rest can conjure grain; old debts and damaged records have their own handover exits.
Evidence-grade content pipeline
All 305 events render headlessly in CI. A balance run walks the full event graph and reports where the economy dead-ends. Every content state has a lifecycle — drafted, validated, integrated, rendered, runtime-seen, manually-played, accepted — and nothing is claimed as done before its stage is proven. The current honest status: the single-run content is estimated at roughly 10 hours per route by simulation models, and the "20+ hours" goal is explicitly not yet accepted.
What the agents actually did
- Content at scale: events, branches, receipts, and endings drafted as structured data, then validated by graph walks — the parts of a life-sim that are pure volume.
- UI iteration under constraints: six layouts across four phone sizes (320→430px) plus large-type mode, verified with same-state before/after captures.
- Runtime evidence: real-time recordings of actual builds reviewed frame-by-frame before features count as done — the pipeline from our flagship guide.
Honest status board
| Area | State |
|---|---|
| Core loop & save system | Playable in Godot, headless-verified |
| All 305 events / 20 endings | Render clean, machine-audited |
| Art & audio | Candidate stage — final human acceptance pending |
| 20-hour content claim | Not accepted (simulation estimates ~10h/route) |
| Device testing & release | Not started — iPhone build pipeline next |
When can I play it?
Not yet — it is in active development. The complete single-player flow runs in Godot today, and iPhone release is the next milestone. Playable demos will appear in this lab first.
Is it really 305 events?
Yes, and they all render in automated tests. What is not yet proven is the total playtime: simulation models estimate roughly ten hours per route, and the team's own bar is twenty. The gap is content depth per branch, not event count.
Why build a life sim with AI agents?
Life sims are almost pure content volume — hundreds of interlocking events where the hard part is consistency, not rendering. That is exactly the work agent pipelines are good at: generate, validate against the graph, and record evidence. See the pipeline guide.