
How we build games
with AI agent teams.
Two real games, one production pipeline: generated art with frame-perfect manifests, contract-driven implementation in Godot, and QA that records evidence for every claim. Here is how it actually works — and where it still breaks.
The short version: agents generate art, write and test code, and collect runtime evidence at a scale one developer cannot match. Humans keep three jobs: deciding what to build, judging what feels good, and accepting what ships. Everything else is pipeline.
Demos are not games — the gap this pipeline exists to close
In 2026, generating a playable prototype takes an afternoon. The industry data shows exactly that: roughly 20% of Steam Next Fest entries now declare generative-AI use, and vibe coding helped push 181,000 mobile games to market in six months. But release counts and hit counts moved in opposite directions — the games earning real revenue barely grew.
The gap is not generation. It is everything after generation: does the UI read on a 390-pixel phone? Does the economy hold for twenty hours? Does the boss fight feel like a fight? Our answer is a pipeline built around one rule: no claim without runtime evidence.
Case study 1: Linjiang Chronicles — a 305-event life simulation
Linjiang Chronicles (一纸青云·临江志) is a premium ancient-life simulation for iPhone, built in Godot 4.6. The numbers at its current development stage: 305 events, 711 choices, 20 endings, 12 characters, 8 chapters, plus sixteen relationship and investigation lines. It is a reading-first game — decisions, materials, consequences — with a paper-and-vermilion UI built for one-handed phone play.
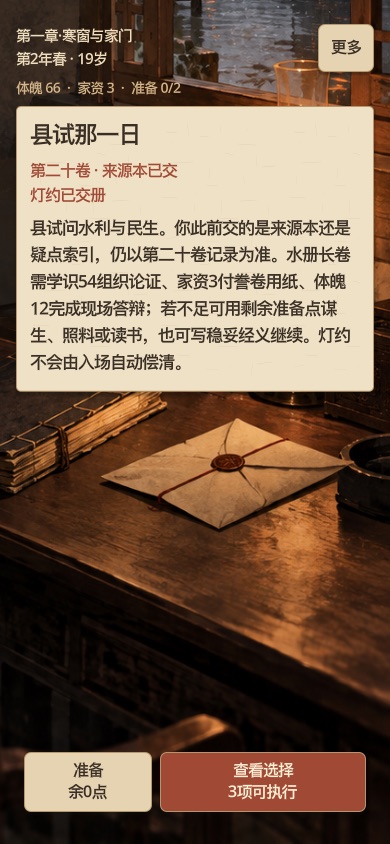
The part that makes this possible: every content branch is simulated headlessly. A balance run walks the full event graph and reports where the economy breaks, where a chapter can dead-end, and how many minutes of genuine content each route holds. When a design claims "twenty hours of content", the pipeline either proves it or flags it. Ours is currently flagged: at least twenty hours of effective single-run content is not yet accepted — the honest state of the project.
Case study 2: Moonlit Kingdom — an idle RPG on its way to iOS
Moonlit Kingdom (月光王国) is an idle RPG about rebuilding a village with heroes and slimes. It is further along the delivery chain: touch-first landscape layouts at 780×360 through 932×430, expedition and dispatch systems, save-state continuity across restarts, and an iOS Xcode project pipeline with source-bound delivery manifests.
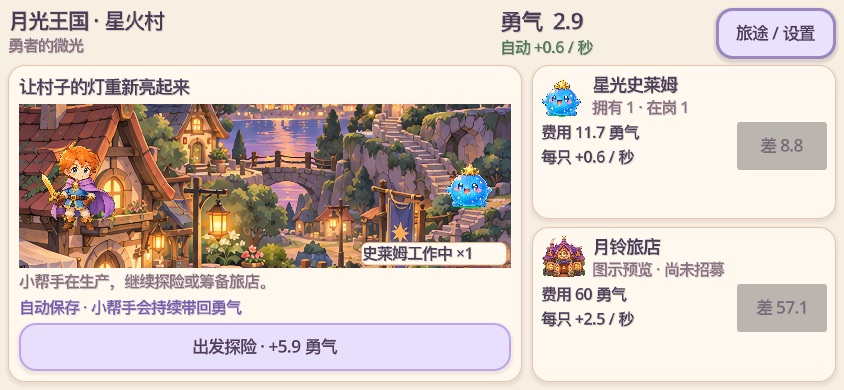
For an idle game, "feels right" lives in tiny details: does the production counter tick when you expect, does the return animation land before the reward toast, does a restart mid-expedition keep the right state. Each of those got its own recorded verification — a real-time capture of the actual build, reviewed frame by frame, before the feature counted as done.
The pipeline, layer by layer
1. Art that ships in a runtime (not pretty pictures)
Game art fails differently from marketing art: it needs alpha edges that survive chroma-keying, anchors that line up across animation frames, and file sizes a phone can load. Our sprite pipeline goes: base identity first → per-state row strips → deterministic background removal → connected-component frame extraction → atlas composition with a frame_layout manifest the engine reads directly. If the manifest and the atlas disagree, the build fails — by design.
2. Implementation under contract
Features are not "asks"; they are contracts with scope, acceptance criteria, and frozen baselines. An agent that changes the dispatch system must prove the other pages still behave — the pipeline runs regression suites over every phone viewport size and flags any drift. This is the unglamorous discipline that separates a shipping game from a demo: frozen interfaces and evidence for every change.
3. QA that records instead of asserting
Every accepted feature leaves behind: a same-state before/after capture, a real-time runtime recording, and a source-bound audit tying the evidence to an exact revision. Reviewers (human or agent) watch the recording, not the promise. When something regresses, the evidence trail shows which change did it.
4. Audio and cinematics
Ambience, SFX, and voice use generated audio with the same rule: files are validated for loudness, loop points, and runtime format before entering the build. Cinematic moments use video-to-frames pipelines — generated video is sliced into engine-ready frame sequences with code-driven timing, not shipped as a video blob the engine can't control.
Where humans still matter
- Taste. Agents can make a UI readable; they cannot decide it feels right. Every "this is fun" verdict is human.
- Cuts. The strongest pipeline output of a week is often a decision to kill a feature. Agents rarely propose killing their own work; humans must.
- Media acceptance. Generated art passes technical checks far more often than aesthetic ones. The acceptance bar for "this character belongs in this world" stays human.
What this costs
Running this pipeline costs API calls, not salaries. A content-heavy simulation like Linjiang Chronicles spends most of its budget on generation and verification loops, not on writing code. The trade is explicit: more compute, fewer people — and more discipline required, because a pipeline without contracts and evidence just produces faster chaos.
Follow the build
This lab publishes the pipeline as it evolves — including failures, cut features, and cost breakdowns. Next up: a deep dive into the sprite atlas pipeline with real manifests, and the full QA loop for the dispatch system. The games will be playable here before anywhere else.
What tools do you use?
Godot 4.6 for the games themselves; image, video, and audio generation models for assets; and a contract-and-evidence workflow (documented in these articles) to keep agent output verifiable. The art and QA approaches are provider-neutral — they work with any generation backend.
Can a solo developer copy this pipeline?
Yes, and it scales down: the core ideas are (1) generate the smallest vertical slice, (2) freeze interfaces once accepted, (3) require runtime evidence for every claim. The upcoming sprite-pipeline article walks through the exact steps.
Is AI doing all the work?
No. Agents do the volume work — generation, implementation, regression testing, evidence collection. Humans own direction, taste, and final acceptance. The honest split is roughly: agents build what you specify; you are responsible for specifying something worth building.